Local coding models, checked by your own tests.
Phonton puts each attempt in a copy of your repo, runs your tests on it, and only shows you a diff that passed. Every run ends with a receipt. Free, open source, no account.
npm install -g phonton-cli- goal
- plan
- edit
- verify
- review
- remember
terminal · phonton 0.25.1runtime download, model pull and calibration
Replay of one recorded run: phonton 0.25.1, qwen3.5:4b on a 4-vCPU runner with no GPU. Text is from the recording; timing is compressed. The test's failure message was written for the demo.
51 exercises. Who said done, and who was right.
Aider Polyglot, 17 exercises each in Python, JavaScript and Rust. Same model for every arm: qwen3.5:4b through Ollama on an RTX 4050 laptop. Tests were visible to all three. Afterwards the original tests were restored and run.
- Bare modelAider's prompt, two tries
- said done
- 43
- wrong when it did
- 37
- tests passed
- 6
- OpenCode 1.14.19run --pure
- said done
- 51
- wrong when it did
- 50
- tests passed
- 1
- Phonton 0.25.0goal --local, the exercise tests as its check
- said done
- 1
- wrong when it did
- 0
- tests passed
- 2
One cell per exercise, 51 in all. said done, tests pass said done, tests fail did not say done
| Language | Phonton passed | Bare passed / said done / wrong | OpenCode passed / said done / wrong |
|---|---|---|---|
| Python | 1 | 2 / 15 / 13 | 1 / 17 / 16 |
| JavaScript | 1 | 4 / 16 / 12 | 0 / 17 / 17 |
| Rust | 0 | 0 / 12 / 12 | 0 / 17 / 17 |
| Kind | Bare | OpenCode |
|---|---|---|
| Wrong output: the tests run and assertions fail | 27 | 29 |
| Crashes on load or uses a missing name | 2 | 11 |
| Does not compile (Rust) | 8 | 10 |
With a 4B model nobody solves much. The bare model passes the most, 6 of 51; Phonton passes 2. The difference is the claim: Phonton said done once, and it was right. The other two said done 94 times, and 87 of those were wrong.
18 Phonton runs stopped on a free-RAM reserve that 0.25.1 lowers for models held in VRAM, and 2 goals were over the 8 KB goal limit. Both count as failures. One JavaScript pass is a refactoring exercise that already passed. Runner: benchmarks/polyglot.
The same run, cut to music.
68 seconds of real recordings: setup, the failed first candidate, the repair, the receipt, then Desktop applying the change.
demo · 68 s · real recordings
phonton 0.25.1 · the TUI
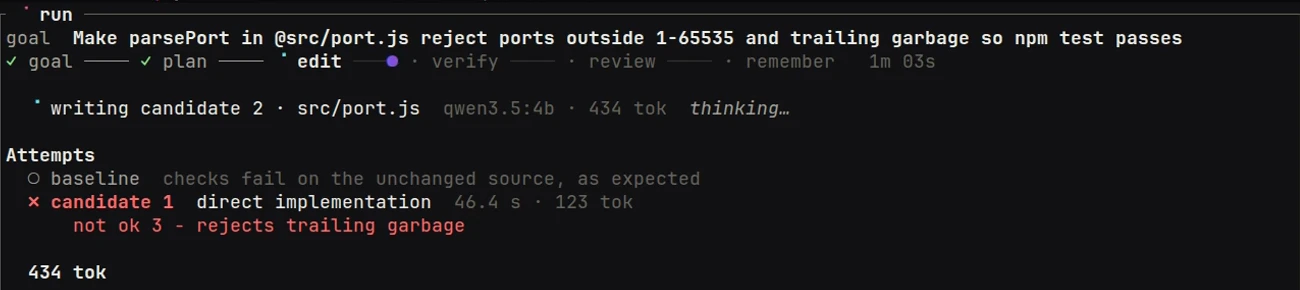
screenshot
Phonton Desktop 0.5.2 · same goal, engine and model
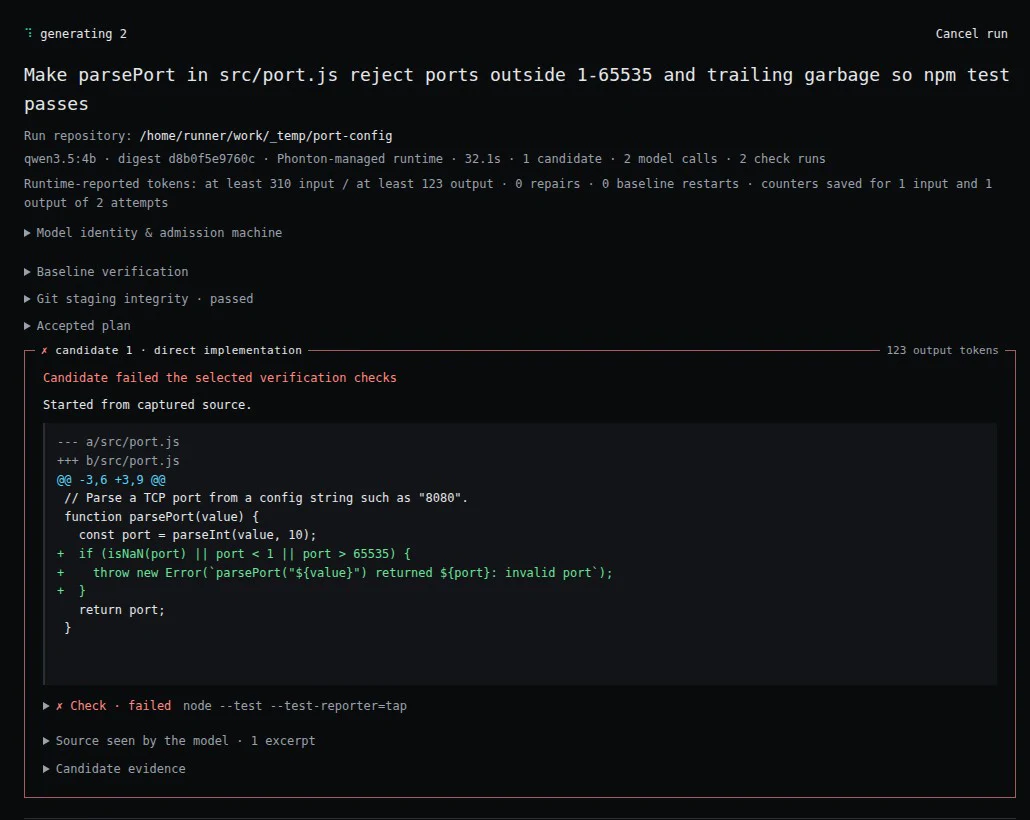
real time
Three commands to a verified diff.
Setup downloads a pinned, hash-checked runtime (about 1.5 GB on Windows and Linux, 160 MB on macOS) and the model, then measures which edit formats it can actually do. No account, no Phonton server, no telemetry.
npm install -g phonton-cli
phonton models setup qwen3.5:4b
cd your-project && phonton
Windows x64 · Linux x64 and arm64 · macOS Apple Silicon and Intel. Read the local models guide
Bigger job? Bring a key.
The same plan, checks and receipt work with Anthropic, OpenAI, DeepSeek, OpenRouter, Gemini or Groq on your own key. Calls go straight to your provider, and the receipt shows the cost.
export ANTHROPIC_API_KEY="..."
phonton doctor --provider
cd your-project && phonton
Or set it in ~/.phonton/config.toml. Provider setup
Also in the box
- plan first
- Files, checks and budget are on screen before any model call. Nothing runs until you approve.
- receipt
- Files, checks, tokens, time, cost and which runtime ran, for every goal.
- real undo
- phonton review reject puts back exactly the files the task changed.
- memory
- Decisions stay on your machine in SQLite, scoped to the repository they came from.